
You want to run a large language model. You don’t have a GPU server. You have a regular CPU-based VPS. Can it actually work, or are you wasting your time and money? The answer is yes, you can run an LLM on a CPU-only VPS. But there are important tradeoffs you need to understand before diving in. This guide breaks down exactly what’s possible, what’s practical, and what’s just not worth attempting on CPU infrastructure.
Can You Actually Run an LLM on a CPU-Only VPS?
Yes, absolutely. CPU inference is not only possible, it’s increasingly practical thanks to optimizations and quantization techniques. You can run small to medium-sized language models on CPU-only infrastructure and get usable results. The key word is “usable.” CPU inference works. It’s just slower than GPU inference. Much slower, in many cases.
A 7-billion parameter model on a GPU responds in 1 to 2 seconds. The same model on a CPU might take 10 to 30 seconds. For some use cases, that’s fine. For others, it’s unacceptable. Understanding when CPU is sufficient versus when you need GPU is crucial for making the right infrastructure choice.
What Is CPU-Only Inference for LLMs?
CPU-only inference means running your language model using only the server’s central processor. No specialized graphics cards. No hardware acceleration. Just pure CPU computation.
When a user sends a prompt to your LLM, the CPU processes that prompt entirely. All the mathematical operations that power the model’s reasoning happen on the CPU. The response is generated and sent back.
This is different from GPU inference, where graphics processing units handle the heavy mathematical lifting much faster.
How Traditional Inference Works
A language model is fundamentally a series of matrix multiplications. Processing a single token through a 7-billion parameter model requires millions of calculations.
On a GPU with thousands of parallel processing cores, these calculations happen simultaneously, completing in milliseconds.
On a CPU with fewer cores (typically 4 to 64), these calculations happen sequentially or in smaller parallel batches, taking much longer. This mathematical reality is why GPU is traditionally faster. It’s not magic or marketing. It’s physics.
Performance Expectations for CPU-Based LLMs
Before deploying a CPU-based LLM, understand realistic performance expectations.
Response Time by Model Size
7-billion parameter model on CPU: 8 to 20 tokens per second. 13-billion parameter model on CPU: 4 to 8 tokens per second. 30-billion parameter model on CPU: 1 to 3 tokens per second. 70-billion parameter model on CPU: 0.5 to 1 token per second.
These speeds assume 4-bit quantization and modern optimizations. Unquantized models are 3 to 5 times slower. A typical response is 50 to 100 tokens. A 7B model takes 5 to 12 seconds. A 13B model takes 12 to 25 seconds. For context, GPT-4 responds in 1 to 3 seconds. A CPU-based 7B model is 5 to 10 times slower.
Throughput (Requests per Hour)
A 7B model on CPU: 10 to 20 requests per hour under optimal conditions. A 13B model on CPU: 5 to 10 requests per hour. A 30B model on CPU: 1 to 3 requests per hour. For comparison, the same model on GPU handles 100 to 500 requests per hour. If you need to serve hundreds of users, CPU inference becomes impractical.
Which Models Are Practical on CPU
Not all models make sense on CPU. Some are too large. Some are too slow. Some fall in the sweet spot where CPU inference is practical.
Practical Models for CPU
Mistral 7B: Smaller, efficient, fast enough on CPU for reasonable use cases.
Llama 2 7B: Decent performance on CPU with 4-bit quantization.
Phi 2.7B: Tiny model, runs on CPU with good speed.
OpenLLaMA 3B: Very small, excellent CPU performance.
Zephyr 7B: Optimized for efficiency, works on CPU.
Practical means you get a response in under 30 seconds, which most users find acceptable.
Problematic Models for CPU
Llama 2 70B LLM model: Too large. Response times of 1 to 5 minutes make it unusable.
Code Llama 34B: Similarly slow on CPU. Better on GPU.
Mixtral 8x7B: Computationally intensive, impractical on CPU.
Anything over 30 billion parameters becomes problematic on CPU unless users are extremely patient.
Optimization Techniques for CPU Inference
You can’t change CPU hardware. But you can optimize your model and software to run faster.
Quantization
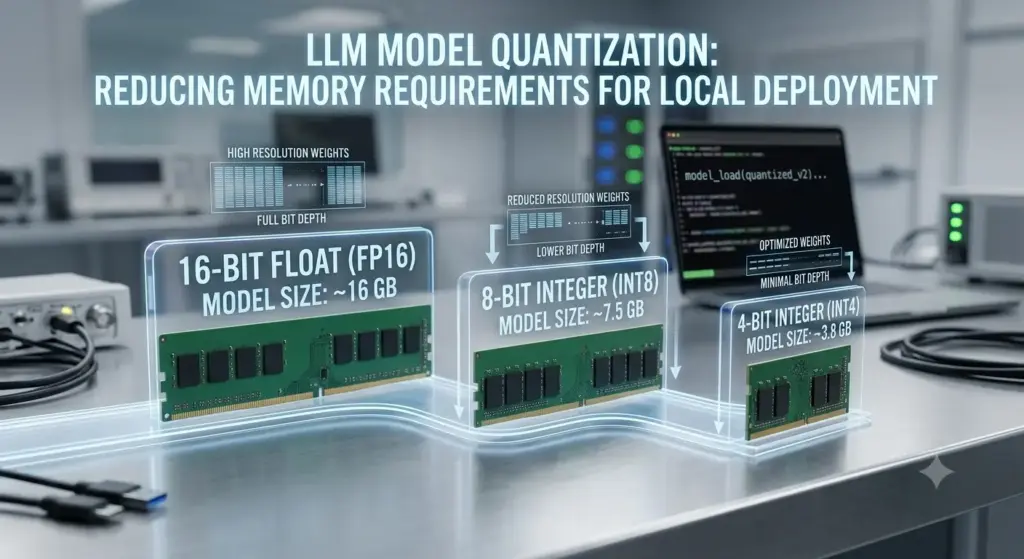
Quantization reduces the precision of your model weights. A 32-bit model becomes 8-bit or 4-bit.
Full Precision (FP32): 7B model = 28 GB RAM needed. Baseline speed: 10 tokens per second.
8-bit Quantization: 7B model = 7 GB RAM needed. Speed: 10 tokens per second (similar speed, much less RAM).
4-bit Quantization: 7B model = 3.5 GB RAM needed. Speed: 8 to 10 tokens per second (slight slowdown, significant RAM savings).
The speedup from reduced RAM is often worth the tiny quality loss.
CPU Optimization Libraries
ONNX Runtime: Optimizes model execution on CPU. OpenVINO: Intel’s library for efficient CPU inference. LLaMA.cpp: Specifically designed for CPU-based LLM inference.
These libraries rewrite computations to use CPU features like AVX-512 more efficiently.
Speed improvements of 2x to 3x are common with proper optimization.
Model Quantization Formats
GGML Format: Optimized for CPU inference. Created specifically for LLaMA.cpp. GPTQ: Works on CPU and GPU with good performance.
INT8: Standard quantization, works everywhere.
GGML format with LLaMA.cpp often gives the best CPU performance.
RAM Requirements for CPU-Based LLMs
RAM is critical for CPU inference. Unlike GPU VRAM, RAM serves both the model and everything else.
A 7B model with 4-bit quantization needs 4 to 5 GB for the model itself. Add 2 to 3 GB for processing overhead. Add 2 to 4 GB for the operating system. Total: 8 to 12 GB RAM minimum.
For 13B models, you need 16 to 24 GB RAM.
For 30B models, you need 32 to 48 GB RAM.
RAM-Conscious Approaches
Use smaller models. A 3B model instead of 7B reduces RAM by 50%.
Maximize quantization. 4-bit instead of 8-bit cuts RAM in half.
Use paging. Move model layers to disk when needed (very slow but works).
Use distributed inference. Split the model across multiple servers.
Real-World Scenarios for CPU-Based LLMs
Scenario 1: Small Business Chatbot with Low Traffic
Business: Local plumbing company needing a chatbot to answer customer questions. Expected traffic: 5 to 10 requests per day. Response time tolerance: Users willing to wait 10 to 20 seconds.
Model choice: Mistral 7B with 4-bit quantization.
Verdict: Absolutely practical. The business saves 90% compared to GPU hosting and gets acceptable performance.
Scenario 2: Internal Tool for a Team
Business: Software company with 20 developers needing AI code assistant for internal use. Expected traffic: 20 to 30 requests per day total. Response time tolerance: Developers willing to wait 15 to 30 seconds.
Model choice: Code Llama 7B with quantization.
Verdict: Practical. The team gets AI assistance without GPU overhead. Lower cost justifies slower response times.
Scenario 3: Public API with Many Users
Business: Online service wanting to add AI features to serve thousands of users. Expected traffic: 1,000+ requests per day. Response time tolerance: Users expect sub-5-second responses.
Model choice: CPU is not suitable. Infrastructure needed: GPU server or scaled distributed CPU setup. Cost: $300+ per month for adequate performance.
Verdict: Not practical on single CPU VPS. GPU or distributed setup required.
CPU vs GPU for LLM Inference
Understanding the tradeoffs helps you choose the right infrastructure.
Speed Comparison
7B model on CPU: 10 tokens per second (6 second response for 50 tokens). 7B model on GPU (NVIDIA A100): 200 tokens per second (0.25 second response). 80 times faster on GPU.
Cost Comparison per Month
CPU VPS (adequate for 7B model): $15 to $30. GPU VPS (adequate for 7B model): $100 to $300. 10 times more expensive for GPU.
When to Choose CPU
Low traffic (under 100 requests per day). Internal tools where speed is not critical. Cost is primary concern. You’re running very small models (3B to 7B). Exploring LLMs without major investment.
When to Choose GPU
High traffic (1,000+ requests per day). User-facing applications where speed matters. Fast response times required (under 2 seconds). Running large models (30B+). Operating at production scale. For most businesses starting with LLMs, CPU is the right choice initially. Switch to GPU once traffic justifies the cost.
Common Mistakes When Running LLMs on CPU
Mistake 1: Choosing a model too large for your CPU. A 30B model on 16 GB RAM VPS will either crash or run at 1 token per second. Choose appropriately sized models.
Mistake 2: Not using quantization. Running full-precision models on CPU wastes RAM and speed. Always quantize.
Mistake 3: Underestimating RAM needs. The model size plus overhead plus operating system exceeds available RAM. Monitor closely.
Mistake 4: Not optimizing the software stack. LLaMA.cpp with GGML format is 2 to 3 times faster than generic PyTorch CPU inference. Choose the right tools.
Mistake 5: Expecting GPU-like performance. CPU inference is fundamentally slower. If you need sub-second responses, you need GPU.
Mistake 6: Not testing with real traffic. A model running fine with one request might struggle with five concurrent requests. Test realistic load.
Mistake 7: Ignoring concurrency limits. CPU with 4 cores can’t handle 100 concurrent requests. Set realistic connection limits.
When CPU Is Actually the Right Choice
CPU-only LLMs are genuinely appropriate in these situations:
You’re building an internal tool for your team. Traffic is low enough that seconds of latency don’t matter. You’re exploring and experimenting, not yet at production scale. Your users are willing to wait (educational tool, research project). Cost is the primary constraint. You’re running very small models (under 10B parameters). You’re starting small and planning to upgrade later.
CPU is not the wrong choice in these scenarios. It’s the practical choice. It’s the cost-effective choice.
Conclusion
Yes, you can run an LLM on a CPU-only VPS. It works. It’s practical for many use cases. It’s cost-effective. But it’s not suitable for every situation.
Choose CPU-based LLM infrastructure if you’re willing to accept slower response times in exchange for dramatically lower costs. Choose GPU if you need fast responses and can justify the higher cost.
For most developers and businesses starting their LLM journey, a CPU-based VPS running a 7-billion parameter model is the perfect entry point. You get to experiment with LLM capabilities without breaking your budget. You learn what’s possible. You make data-driven decisions about whether to scale up to GPU infrastructure later.
The future of AI isn’t exclusively GPU-based. CPU inference keeps improving. Quantization techniques keep advancing. Optimization libraries keep getting better. Running LLMs on CPU becomes increasingly practical each year.Start with CPU. Scale to GPU when justified. This pragmatic approach builds sustainable AI infrastructure for your business.
Start Running Your LLM on Ucartz VPS Today
Ucartz Cloud VPS gives you the infrastructure to run LLMs affordably. From our entry-level 8 GB VPS ($14.99/month) for 7B models to our 32 GB servers for larger models, find the right tier for your workload. Deploy in minutes. Scale anytime. View Ucartz VPS Plans and start experimenting with LLMs today.
Frequently Asked Questions
Can I run GPT-3 scale models on CPU?
No. Models with 100B+ parameters need 300+ GB RAM even with quantization. Impractical on any VPS. Use a dedicated enterprise server or GPU.
Will my CPU overheat running LLMs continuously?
Modern CPUs throttle if too hot. Monitor temperatures. Good airflow in the data center prevents issues. Ucartz managed servers handle thermal management.
Can I run multiple concurrent requests on CPU?
Only a few at a time. A 4-core CPU might handle 2 to 4 concurrent requests comfortably. Don’t expect high concurrency.
Is CPU inference suitable for production?
Yes, if your traffic and response time requirements fit. Many production services use CPU for lower-traffic applications.
Can I upgrade from CPU to GPU later?
Yes. You can migrate your model and application to GPU infrastructure later when needed.
Should I use LLaMA.cpp or other software?
LLaMA.cpp is optimized for CPU and usually fastest. Ollama is easier to use but slower. Choose based on your needs.
How do I monitor CPU utilization?
Use standard Linux tools like top, htop, or your hosting provider’s dashboard. Monitor CPU usage, RAM usage, and temperatures.